In order to do math on a computer, you should have some idea of how computers represent numbers and do computations.
Unlike strongly typed languages (e.g. C), you don’t have to worry too much about type if you’re just scripting. However, you will have to think about this for many algorithms in scientific computing.
x = 5 # an integer type
print(type(x))
x = 5.0 # float type
print(type(x))
print(4/3) # division of ints -> float
print(4//3) # integer division -> intBits and Bytes
A bit is a 0/1 value, and a byte is 8 bits. Most modern computers are 64-bit architectures on which Python 3 will use 64-bits to represent numbers. Some computers may be 32-bit architectures, and Python may use 32-bits to represent numbers - beware!
You can represent strings of bits using the 0b prefix. Be default, these will be interpreted as integers written in base-2. For example, on a 32-bit system,
0b101 = 00000000000000000000000000000101 (base 2) = 5 (base 10)x = 0b101
print(x)It is often easier to deal with hexadecimal (base-16), denoted with the 0x prefix
x = 0xF
print(x)
Let’s count in hexadecimal and binary:
print("hex\tbin\tdec")
for x in range(0x11):
    print("{:x}\t{:b}\t{}".format(x, x, x))
0xF == 0b1111 == 15By using the 0o prefix, you can also use octal (base 8) if you’d like
x = 0o10
print(x)
hexadecimal is often used because it breaks up bits into blocks of 4 (16 = 2^4). So a 64-bit type has some representation as a length-16 string in hexadecimal.
Integers
Integers are represented in base-2 using bits. Most modern computers are 64-bit architectures, and Python 3 will by default use 64-bit integers. However, unlike some languages, Python will use arbitrary precision so you don’t run into overflow errors:
print(2**65) # ** for exponentiationimport sys
sys.getsizeof(2**256) # size in bytesHowever, when we call code written in C/C++ or fortran such as numpy, you can run into overflow issues
import numpy as np
x = np.int64(2)
x ** 63x**65Bitwise operations
You can perform operations on bit strings in Python. To start with, we recall operations in boolean algebra: & (and), | (or), and ^ (xor) ~ (not).
Here’s a list of possible values for &
for i in [0,1]:
    for j in [0,1]:
        print("{} & {} = {}".format(i,j,i&j))
Performing an operation bitwise just performs the operation on each set of bit grouped by position (i.e. you can read off each column of the below using the table above)
  0b1100
& 0b0101
--------
  0b0100
def binprint(n):
"""
formats an input integer n to 4 digit binary
n input
prints n
"""
print("{:04b}".format(n)) # 4 digits, padded by 0 in the front
print("the binprint function simply formats a number in binary and zero-pads on the left up to 4 digits")
binprint(1)
binprint(2)
binprint(4)
binprint(8)
print("\n")
print("bitwise operations")
binprint(0b1100 & 0b0101) # bitwise and
binprint(0b1100 | 0b0101) # bitwise or
binprint(0b1100 ^ 0b0101) # bitwise xor
binprint(~0b1100) # negationNote that & and and are not equivalent. and does not operate bitwise - it interprets both as logical values (where 0 is False and any other number is True).
binprint(0b1100 & 0b0101)
binprint(0b1100 and 0b0101)
Two’s Complement
You’ll notice in the above, that ~ has a potentially unexpected output. We might have expected something like the following:
binprint(~0b1100 & 0b1111) # negation, with bitmask for last 4 digitsTo explain why, we need to understand how negative integers are represented. Let’s consider a signed 8-bit integer. The first bit is the sign bit (0 indicates the number is positive, and 1 indicates the number is negative).
try:
    import bitstring
except ImportError:  # not preinstalled on Google Colab
    %pip install -q bitstring
    import bitstring


def print_int8(a):
    """
    print a as if it were an 8-bit signed integer
    """
    # for printing color
    CRED    = '\33[31m'
    CBLUE   = '\33[34m'
    CEND      = '\33[0m'

    b = bitstring.BitArray(int=a, length=8)
    bs = str(b.bin)
    print(CBLUE + bs[0] + CEND + CRED + bs[1:] + CEND)

print_int8(1)
print_int8(8)
print_int8(64)
print_int8(127)
What about a negative number?
print_int8(-1)
print_int8(-127)
Naively, if we ignore the sign bit, -1 looks like "-"127, and -127 looks like "-"1. This is because negative integers are using two’s complement to represent negative integers, so you can’t just read off the number by ignoring the sign bit in the way you might expect.
You can compute the two’s complement of a number by inverting bits using a bit-wise not operation and adding 1 (ignoring integer overflow).
print_int8(~4 + 1)
print_int8(-4)
The two’s complement operation is its own inverse.
def twos_complement(n):
    """
    compute the two's complement of an integer n
    """
    return ~n + 1

n = 4
print_int8(4)
print_int8(twos_complement(4))
print_int8(twos_complement(twos_complement(4)))
Note that positive numbers can go up to 127, but negative numbers go down to -128.
print_int8(0)
print_int8(127)
print_int8(-128)
Why use two’s complement? The reason why is that using this representation you can use the same circuits in hardware for addition, subtraction, and multiplication of negative integers that you can for positive integers.
Floating Point Numbers
Real numbers are typically represented as floating point numbers on a computer. Almost all real numbers must be approximated, which means you can’t always ask for exact equality
1.0/3.0# A classic floating point number example
0.1 + 0.2print(1.2 - 1.0)
print(1.2 - 1.0 == 0.2)
print(np.isclose(1.2 - 1.0, 0.2)) # Use isclose() method for comparison The approximation error is called machine precision, typically denoted
print(np.finfo(np.float16).eps) # 16-bit float
print(np.finfo(np.float32).eps) # 32-bit float
print(np.finfo(np.float64).eps) # 64-bit float
# print(np.finfo(np.float128).eps) # 128-bit float, might not be available depending on your machine.
32-bit floating point numbers corrsepond to a float in C, and are also known as single precision numbers. 64-bit floating point numbers correspond to a double in C, and are also known as double precision numbers. 16-bit floats are half-precision, and 128-bit floats are quad-precision.
Double precision is the standard for many numerical codes. Quad- (or higher) precision is sometimes useful. A big trend in deep learning is to use lower-precision formats.
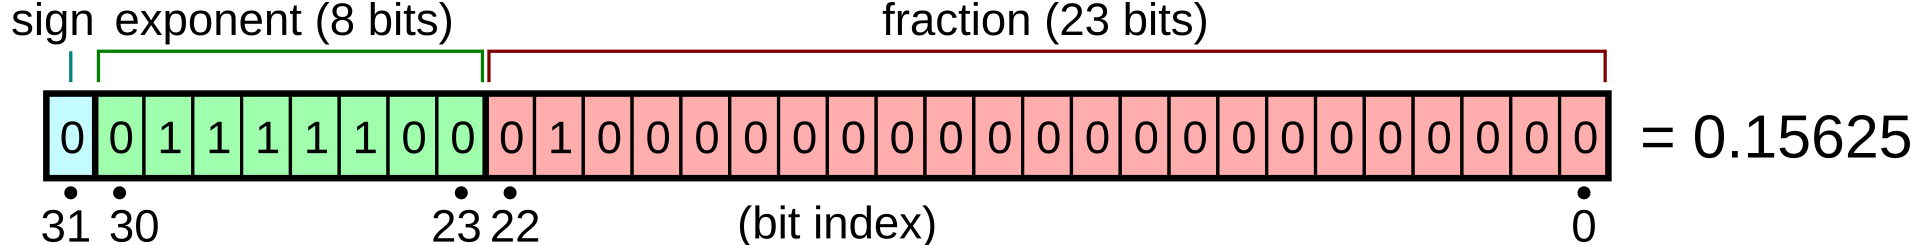
Floating point numbers are numbers written in scientific notation (in base-2). They contain a sign bit, a set of bits for the exponent, and a set of bits for the decimal (called the significand or mantissa).
For example, float32 has 1 bit for the sign, 8 bits for the exponent, and 23 bits for the mantissa.
For further reading on potential considerations with floating point numbers, see the Python documentation.
You can inspect the bits used in a floating point number in python using the bitstring package
(pycourse) $ conda install bitstring -c conda-forge(this notebook installs it with pip if it is missing, e.g. on Google Colab)
def fmt_float32_bits(a):
    """
    prints bits of a 32-bit float
    """
    # for printing color
    CRED    = '\33[31m'
    CGREEN  = '\33[32m'
    CBLUE   = '\33[34m'
    CEND      = '\33[0m'

    b = bitstring.BitArray(float=a, length=32)
    bs = str(b.bin)
    return CBLUE + bs[0] + CEND + CGREEN + bs[1:9] + CEND + CRED + bs[9:] + CEND

print("{: .2e} = {}".format(1.0, fmt_float32_bits(1.0)))
print("{: .2e} = {}".format(-1.0, fmt_float32_bits(-1.0)))
print("{: .2e} = {}".format(1/(2**126), fmt_float32_bits(1/(2**126))))
print("{: .2e} = {}".format((2**126),fmt_float32_bits((2**126))))
print("{: .2e} = {}".format((np.pi),fmt_float32_bits((np.pi))))Converting From Floating Point
If you want to convert the binary floating point representation to a decimal, you can read off the sign, exponent, and significand independently.
The sign bit is straightforward (0 is positive, 1 is negative). For floats, there are two equivalent zeros.
print(" 0.0 = {}".format(fmt_float32_bits(0.0)))
print("-0.0 = {}".format(fmt_float32_bits(-0.0)))
The exponent has a “bias” equal to half the number of possible bits. So to get the value of an 8-bit exponent, we subtract 2**7-1 = 127 = 0b01111111. So the exponent part is
for x in [2**-126, 2**-30, 1e0, 2**10, 2**126]:
    print( "{:.2e} = {}".format(x,fmt_float32_bits(x)))
The decimal multiplies the exponential by
for x in [8, 9, 10, 11, 12]:
print( "{:02} = {}".format(x,fmt_float32_bits(x)))Caution!
You can’t count on floating point numbers to count:
a = np.float32(2**24 + 1)
b = np.float32(2**24)
print(a - b)
print("a = {}".format(fmt_float32_bits(a)))
print("b = {}".format(fmt_float32_bits(b)))You must also be aware of accumulating rounding errors. Let’s test that by taking an average of many duplicates of 1/3.
floatype = np.float32
x = floatype(0)
samp = floatype(1./3.) # be sure that samples are in the same precision
nsamp = 10**6 # how many samples
for i in range(nsamp):
  x = x+samp
x = x/nsamp
print("Error in the mean is {:.2e}".format(x-samp))
There other ways to compute means, but they don’t do much better
x = floatype(0)
for i in range(nsamp):
  x = x*floatype(i/(i+1))+samp/floatype((i+1))
print("Error in the mean is {:.2e}".format(x-samp))
You obtain the number by raising the significand to the base multiplied by the exponent.
Print Formatting
It is often convenient to format floating point numbers for printing without showing full precision. An explanation of available options can be found in the format specification mini-language documentation. We’ll cover a few examples.
When formatting a floating point number with format, you put format specification in the curly braces {}, as in "{:width.precision}}.
The width denotes the total field width.
The precision denotes how many digits should be displayed after the decimal.
pi = np.pi
print("{:e}".format(pi))      # exponential notation
print("{:.2e}".format(pi))    # exponential, precision 2
print("{:f}".format(pi))      # fixed-point notation
print("{:.2f}".format(pi))    # fixed-point, precision 2
print("{:6.2f}".format(pi))   # minimum field width of 5
print("{:+6.2f}".format(pi))  # minimum field width of 5, explicit sign
print(f"{pi:+6.2f}")          # f-string instead of format
print("{:06.2f}".format(pi))  # 0-pad to to fill width
print("{: .2f}".format(pi))   # use space for sign alignment
print("{: .2f}".format(-pi)) # use space for sign alignmentExercise
What is for 32 and 64-bit floats? (hint: use
np.log2)How many bits do you think are used to represent the decimal part of a number in both these formats?
If you take into account a sign bit, how many bits are left for the exponent?
What is the largest exponent you can have for 32- and 64-bit floats? Keep in mind that you should have an equal number of positive and negative expoenents.
Design an experiment to check your answer to part 4.
Check your answer with e.g. np.finfo(np.float32).max)
# Your code here
Notebook Cell
# Part 1
print(np.log2(np.finfo(np.float32).eps))
print(np.log2(np.finfo(np.float64).eps))
Notebook Cell
# part 2
print(-np.log2(np.finfo(np.float32).eps))
print(-np.log2(np.finfo(np.float64).eps))
Notebook Cell
# Part 3
32 + np.log2(np.finfo(np.float32).eps) - 1
Notebook Cell
# part 4
print(0b11111111 // 2) # bit string of 8 1s in binary
print(0xFF // 2)       # same bit string, but in hex
Notebook Cell
# part 5
print(np.float32(1.0 *2**127))
print(np.float32(1.0 *2**128))
Notebook Cell
np.finfo(np.float32).max